Behind the Canvas: The Embedding Architecture of Retrievals
How Retrievals compares your descriptions with artwork images to find related works from the National Gallery of Art.
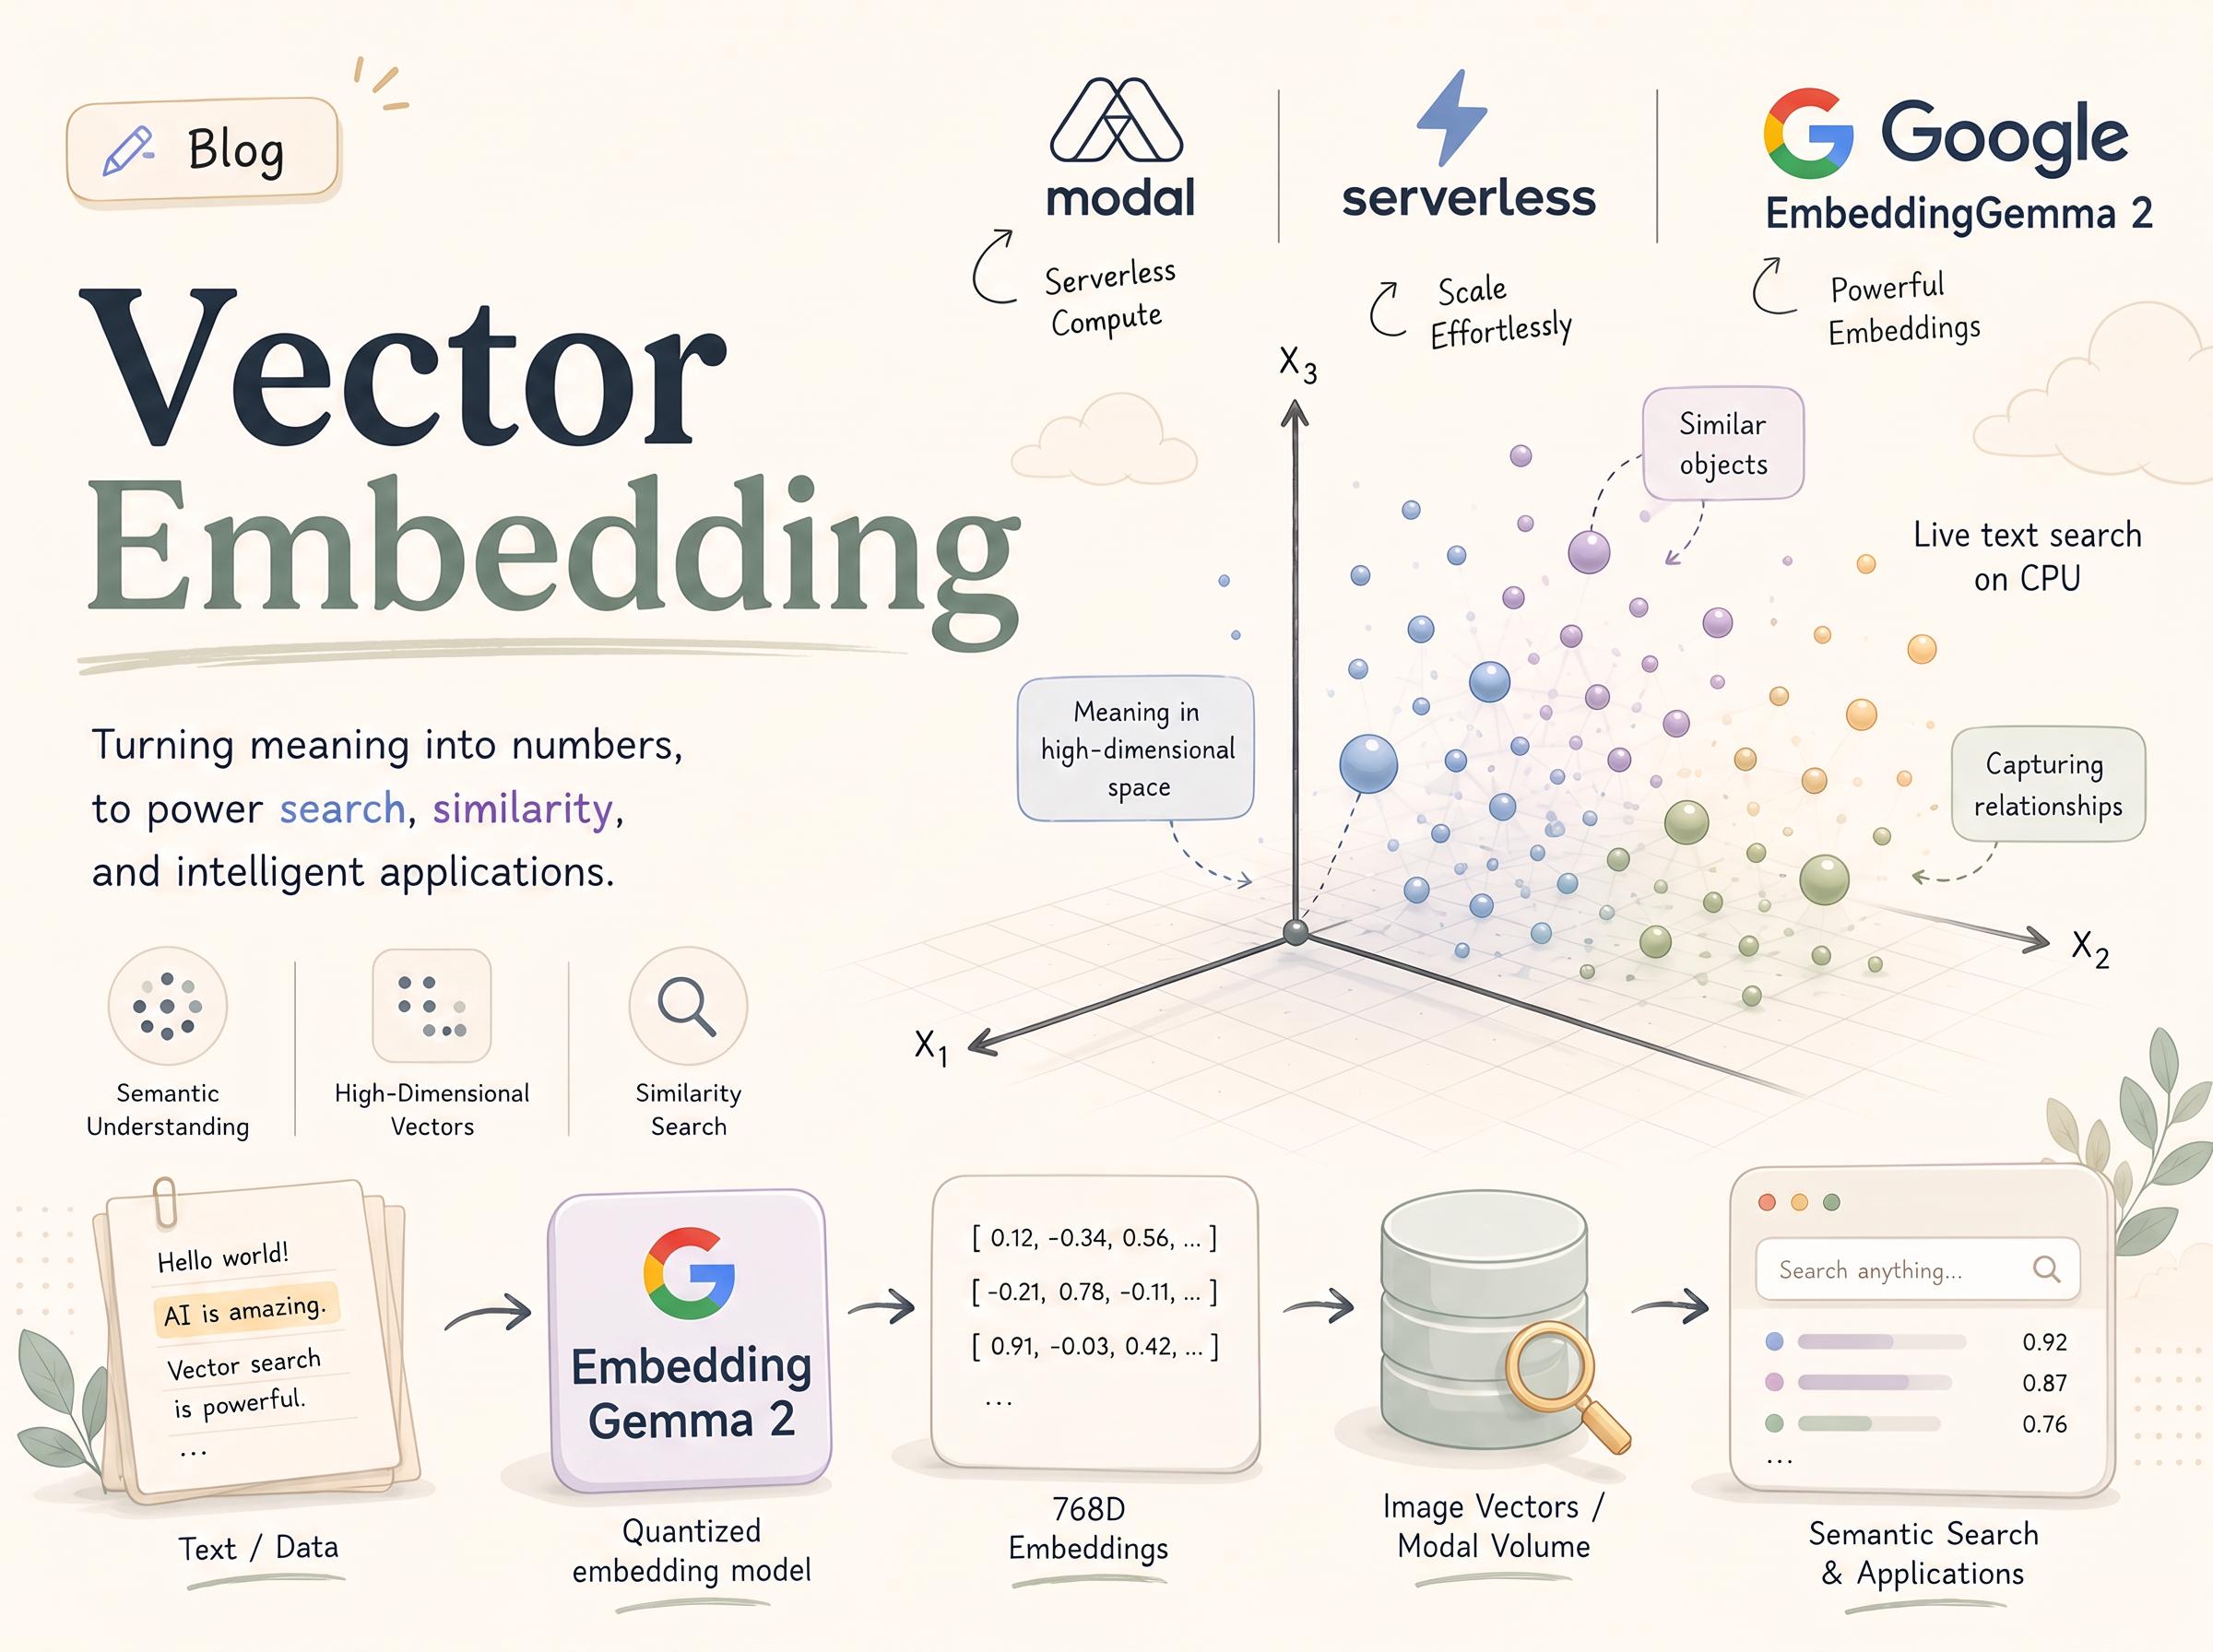
Updated 24 October 2026. Retrievals searches 40,368 curated images from the National Gallery of Art's 68,816-object open-access dataset. Here is what happens between describing an artwork and seeing the results.
Preparing the collection
Before anyone searches, Google's EmbeddingGemma 2 model turns each artwork image into a numeric description called an embedding. Images with similar visual qualities can have similar embeddings.
We prepare these descriptions ahead of time and store them with each artwork's title, artist, date, and museum link. Search can then compare these descriptions without processing every image again.
flowchart LR
    A["Artwork images"] --> B["Model creates numeric descriptions"]
    B --> C[("Searchable artwork collection")]
Matching your description
After signing in, you can describe a scene, a mood, a color, or something you remember. The same model turns your words into an embedding that can be compared with the artwork embeddings.
Retrievals compares your description with all 40,368 indexed images and ranks the closest matches. This is why you can search with a phrase such as "a lonely boat on dark water" without knowing an artist's name or the catalog title.
flowchart LR
    A["Your description"] --> B["Model creates a numeric description"]
    B --> C["Compare with the artwork collection"]
    D[("Prepared artwork descriptions")] --> C
    C --> E["Show the closest matches"]
Browsing more results
A search returns up to 64 matches. The page shows them in smaller groups as you scroll. Beyond that first set, you can browse 16 more at a time, up to 256 ranked results.
Those later pages reuse the description already created for your search. The model does not need to process your words again each time you scroll.
Keeping image preparation separate
Processing the artwork collection is a separate job from answering a search. The image preparation uses a GPU, while live text searches run on CPU. That leaves each search with two tasks: describe your text numerically and compare it with the prepared collection.
The results are similarity matches, not a definitive identification. Open an artwork and check its linked museum record when you need to confirm details.